
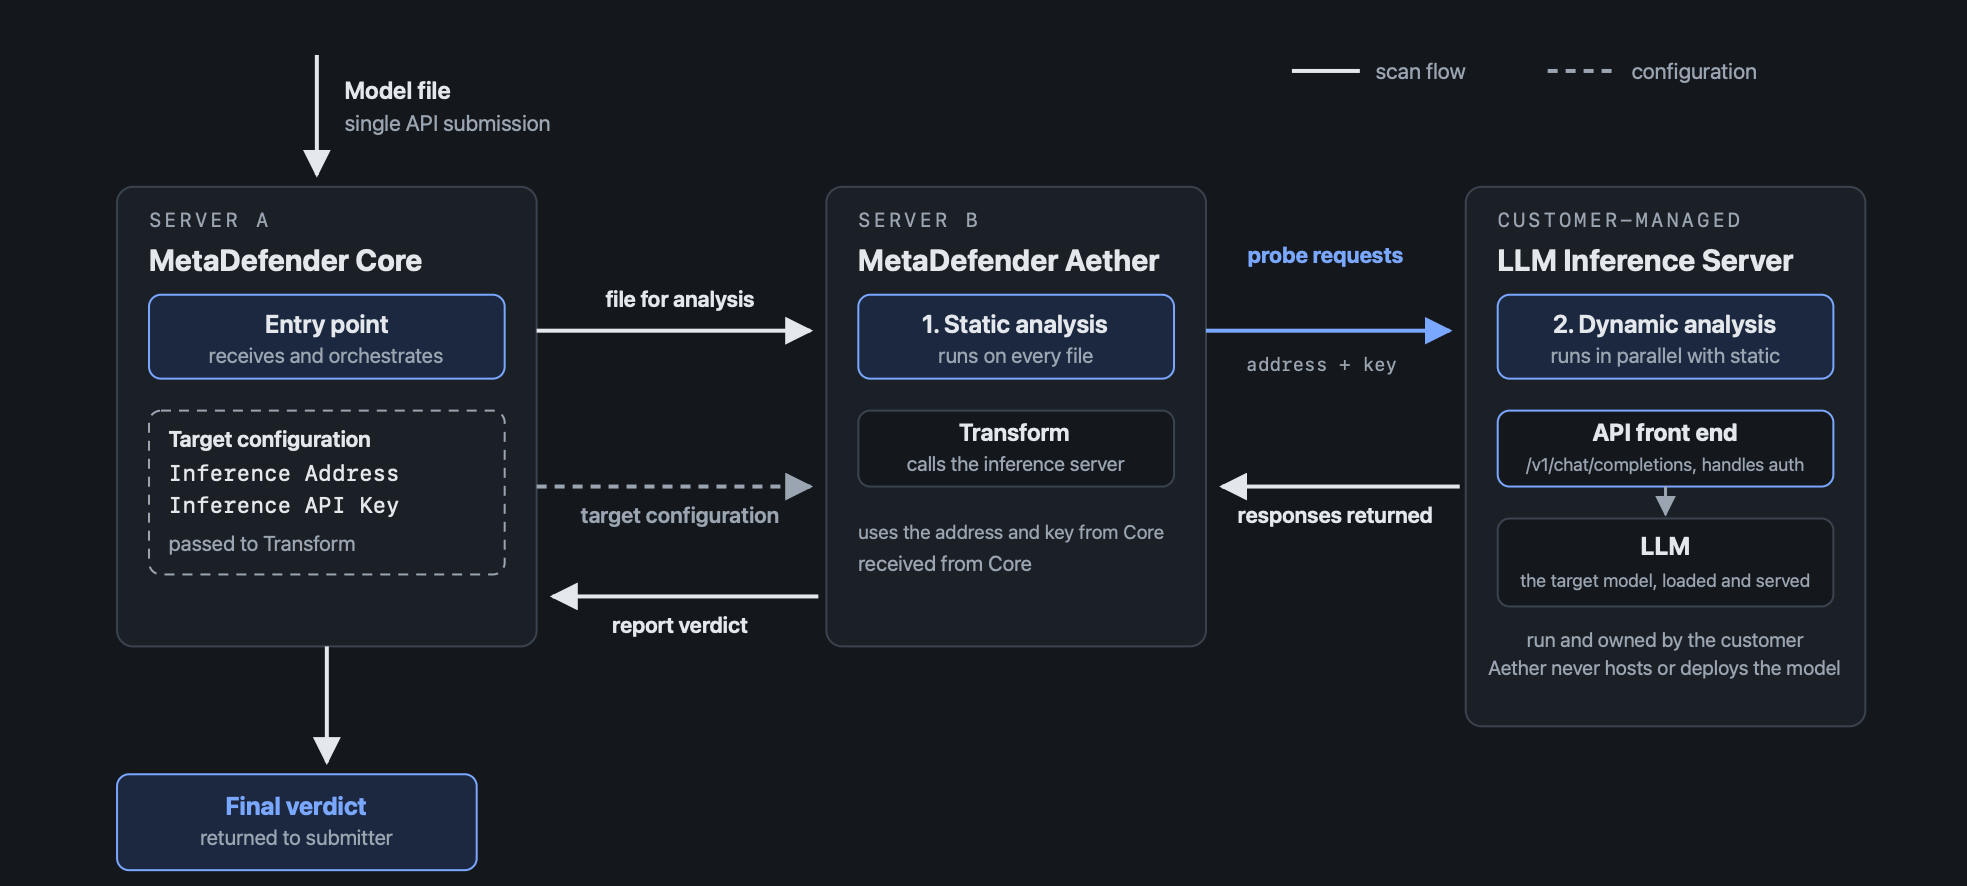
In dynamic scanning, MetaDefender Aether sends probe requests to a running LLM and judges the responses. Aether does not host or deploy the model. The model runs on a customer-managed host, the LLM Inference Server, which can be a physical server, a virtual machine or a container, on premises or in a private cloud.
Any inference server with an OpenAI-compatible chat completions API can act as the LLM Inference Server, for example:
vLLM
Ollama
Hugging Face TGI
NVIDIA NIM or Triton
LM Studio
llama.cpp (
llama-server)LocalAI
A gateway such as LiteLLM can sit in front of any of them. Aether cannot be installed on the LLM Inference Server. They are always separate machines, so the LLM Inference Server must expose its API on the network.
The target architecture required for this feature is outlined below:
Setup steps
Follow the sections in order:
Section | Task |
|---|---|
Sizing the LLM Inference Server | Provide enough memory to hold the model. |
Requirements: OpenAI-compatible API and chat model | Serve a chat-capable model on |
Requirements: Network reachability | Make the endpoint reachable from the Aether host. |
Requirements: Model name | Serve the model under the scanned file's name, without the extension. |
Requirements: Authentication | Add a Bearer key, if the endpoint needs one. |
Configuration Details | Configuring the environment. |
Verifying the configuration | Test the endpoint before scanning. |
Example: vLLM behind a LiteLLM proxy | Optional: a complete reference setup. |